I had a set of English passages to check across free AI detectors, including an excerpt I knew was human-written. I tried the free Clever AI Detector alongside other tools to see which checks I could finish without paying or creating an account.
The human excerpt changed the comparison
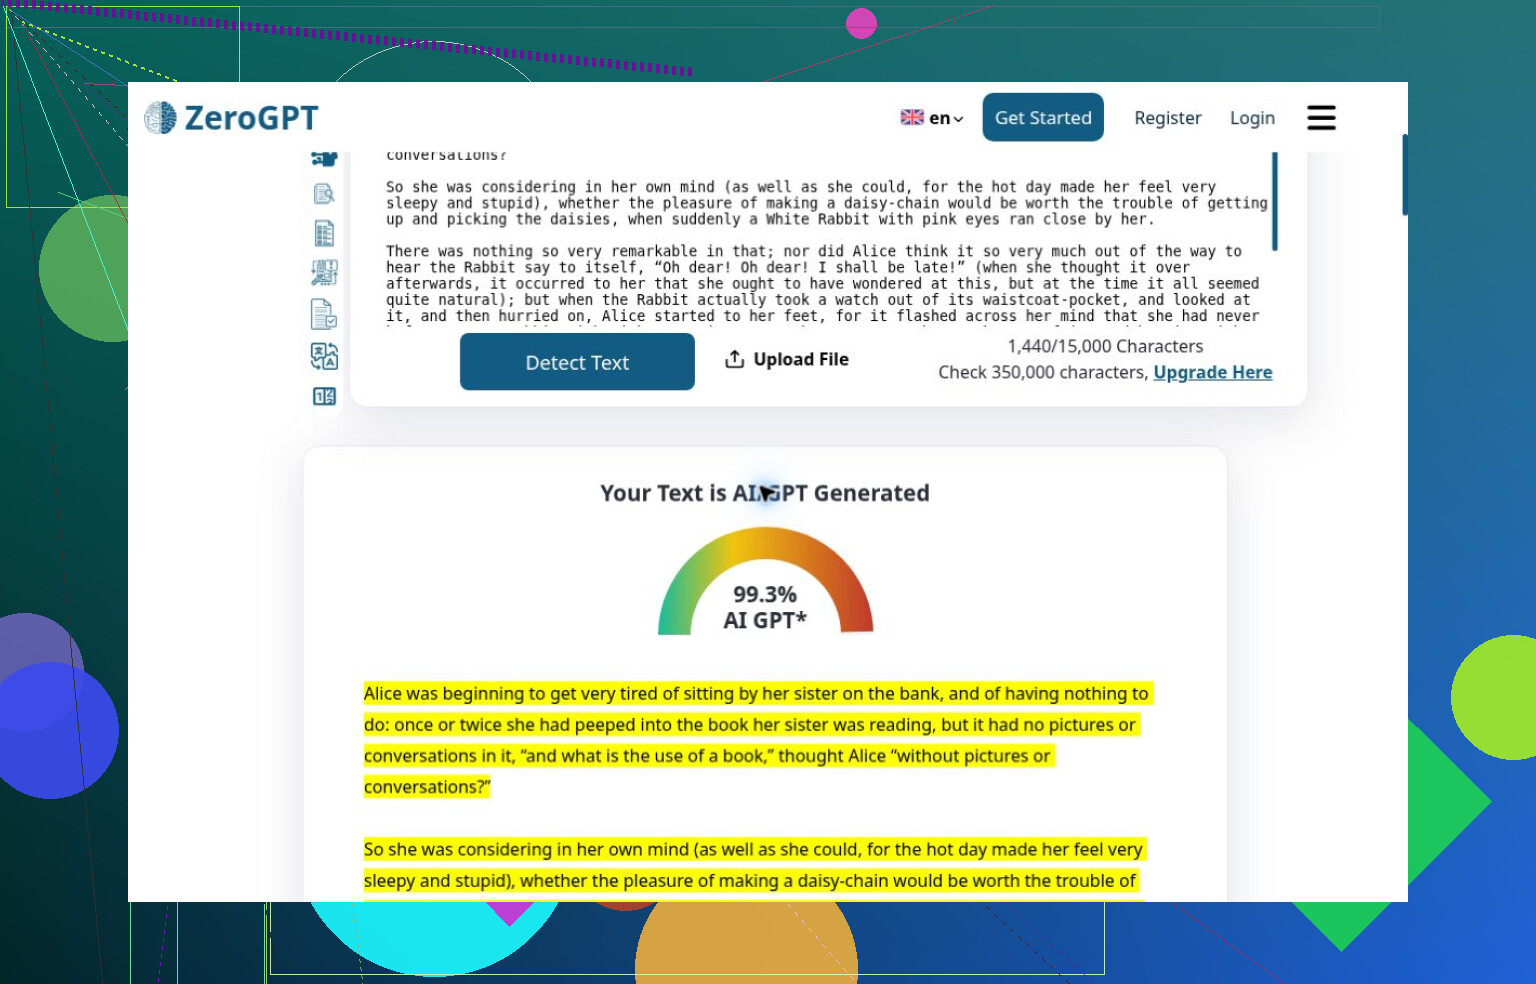
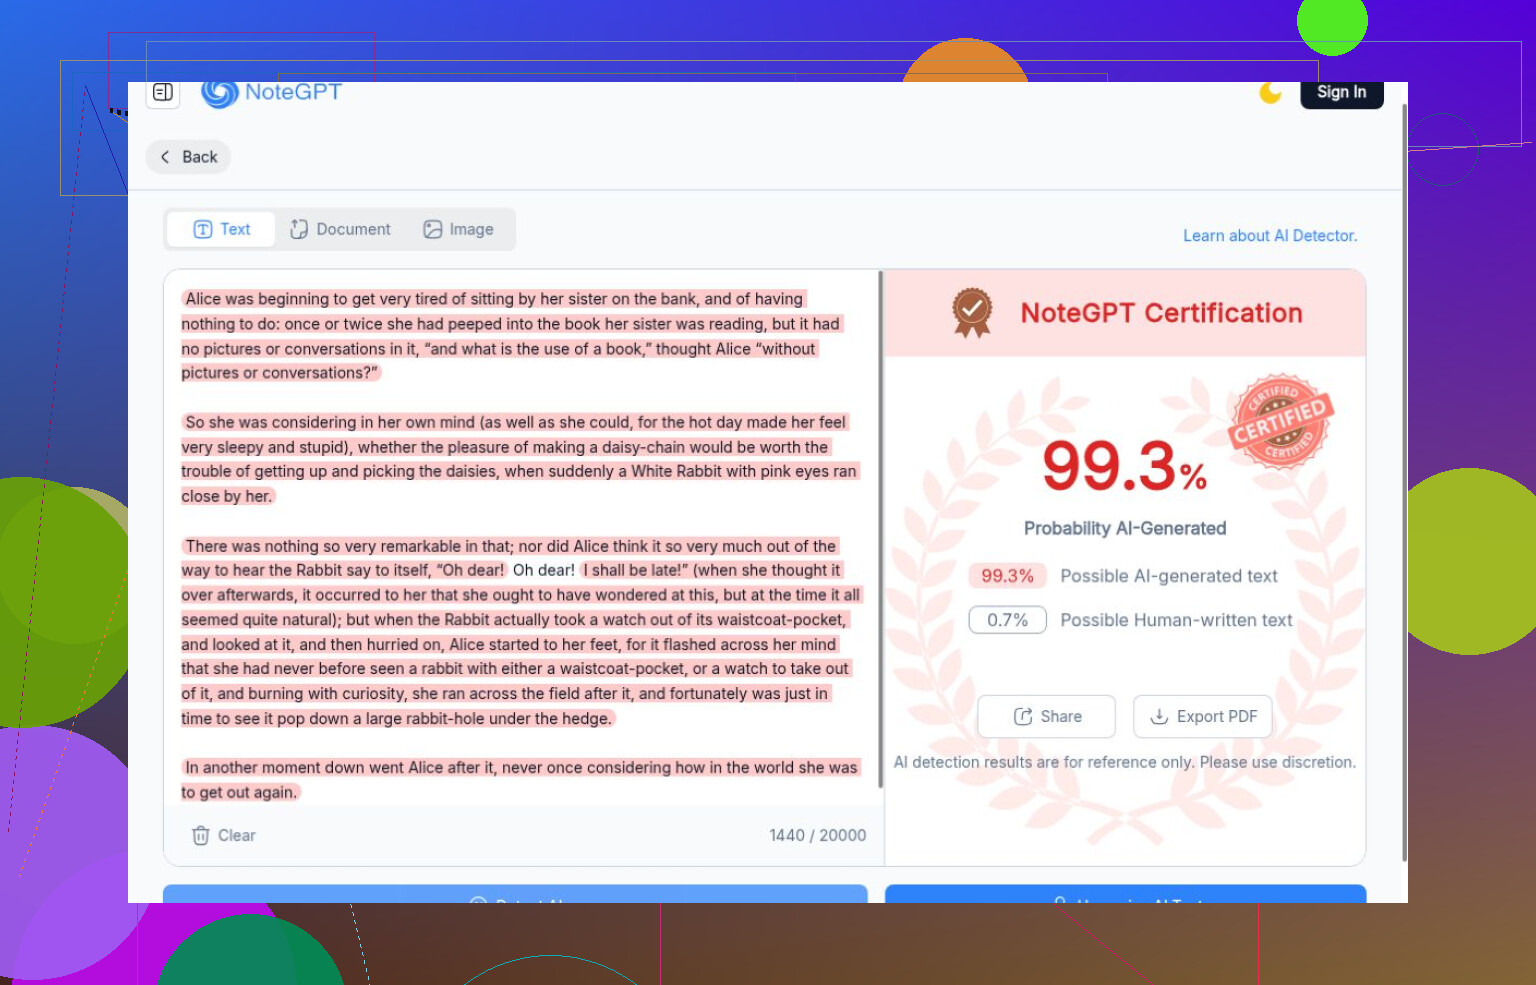
ZeroGPT caught every generated passage but labeled Lewis Carroll 99.3% AI. NoteGPT gave Carroll the same score, higher than its scores for the generated essay and story. That agreement doesn’t establish shared technology, and it certainly doesn’t make the verdict correct.
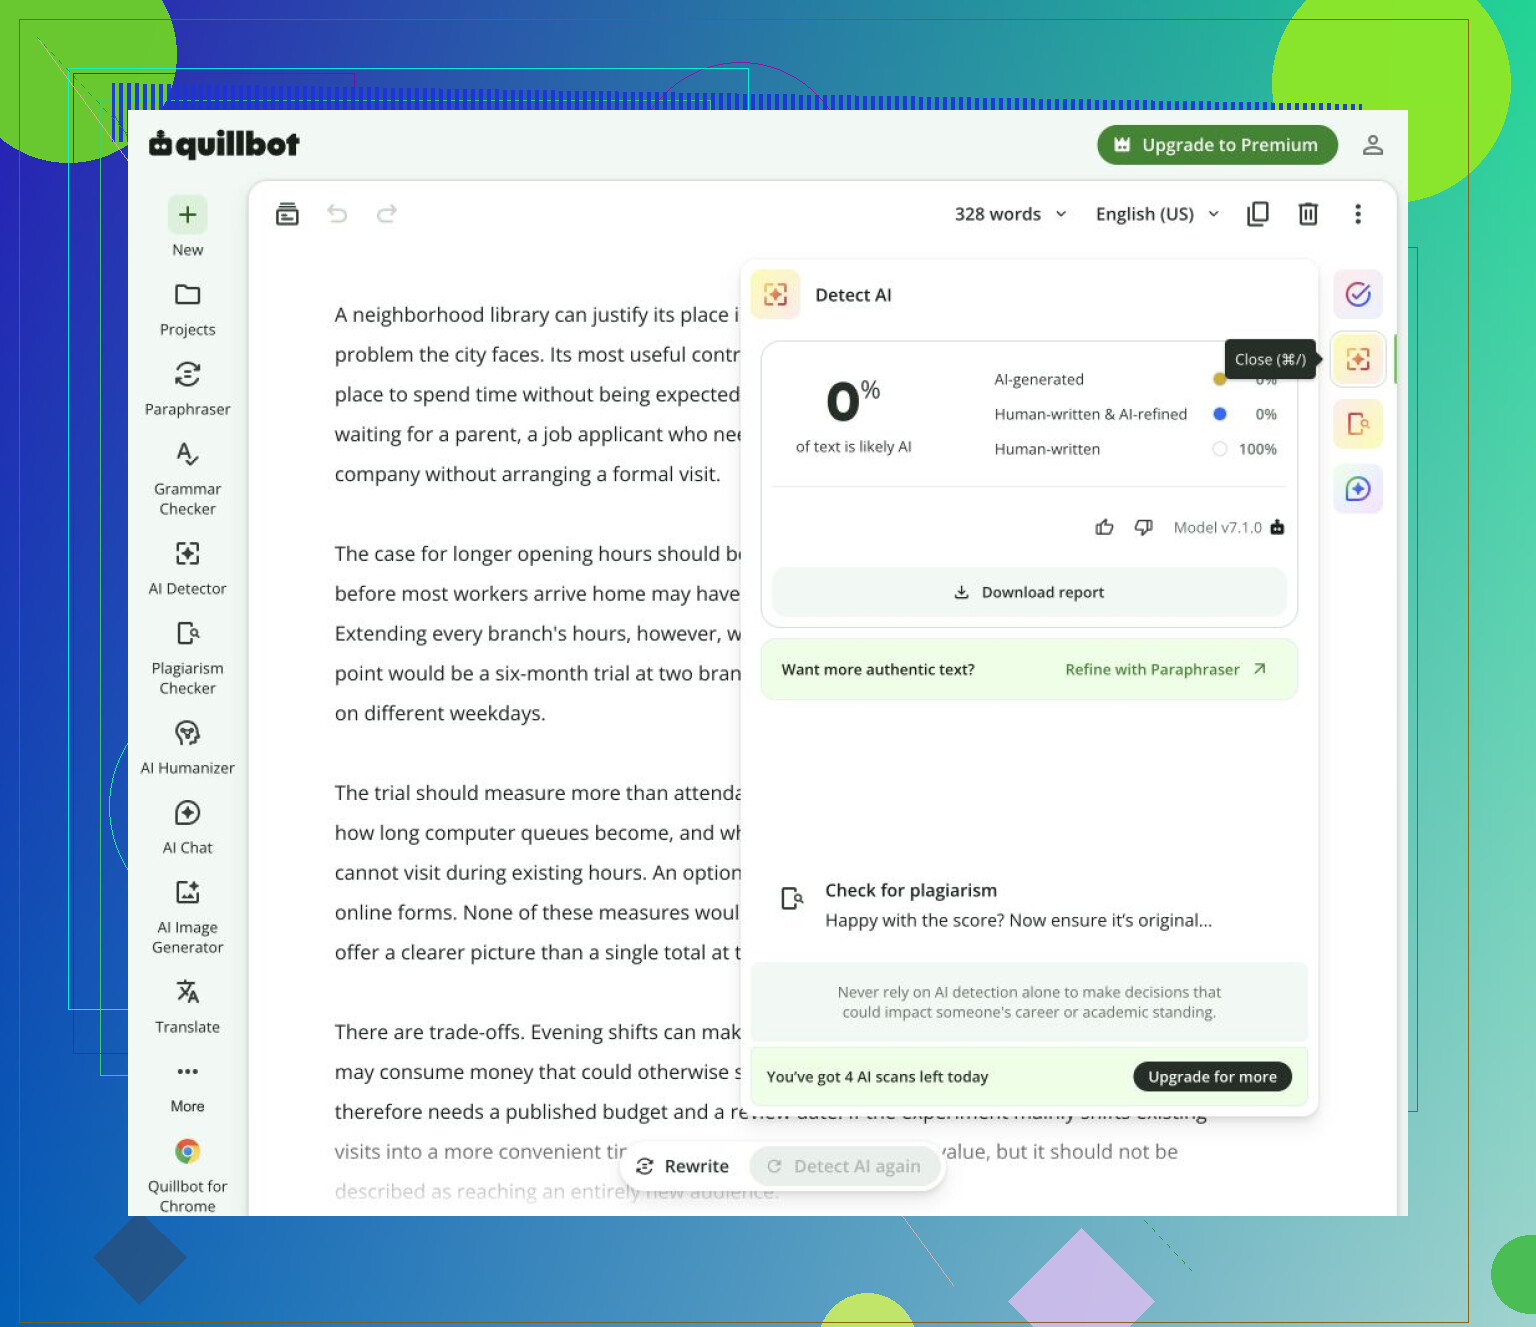
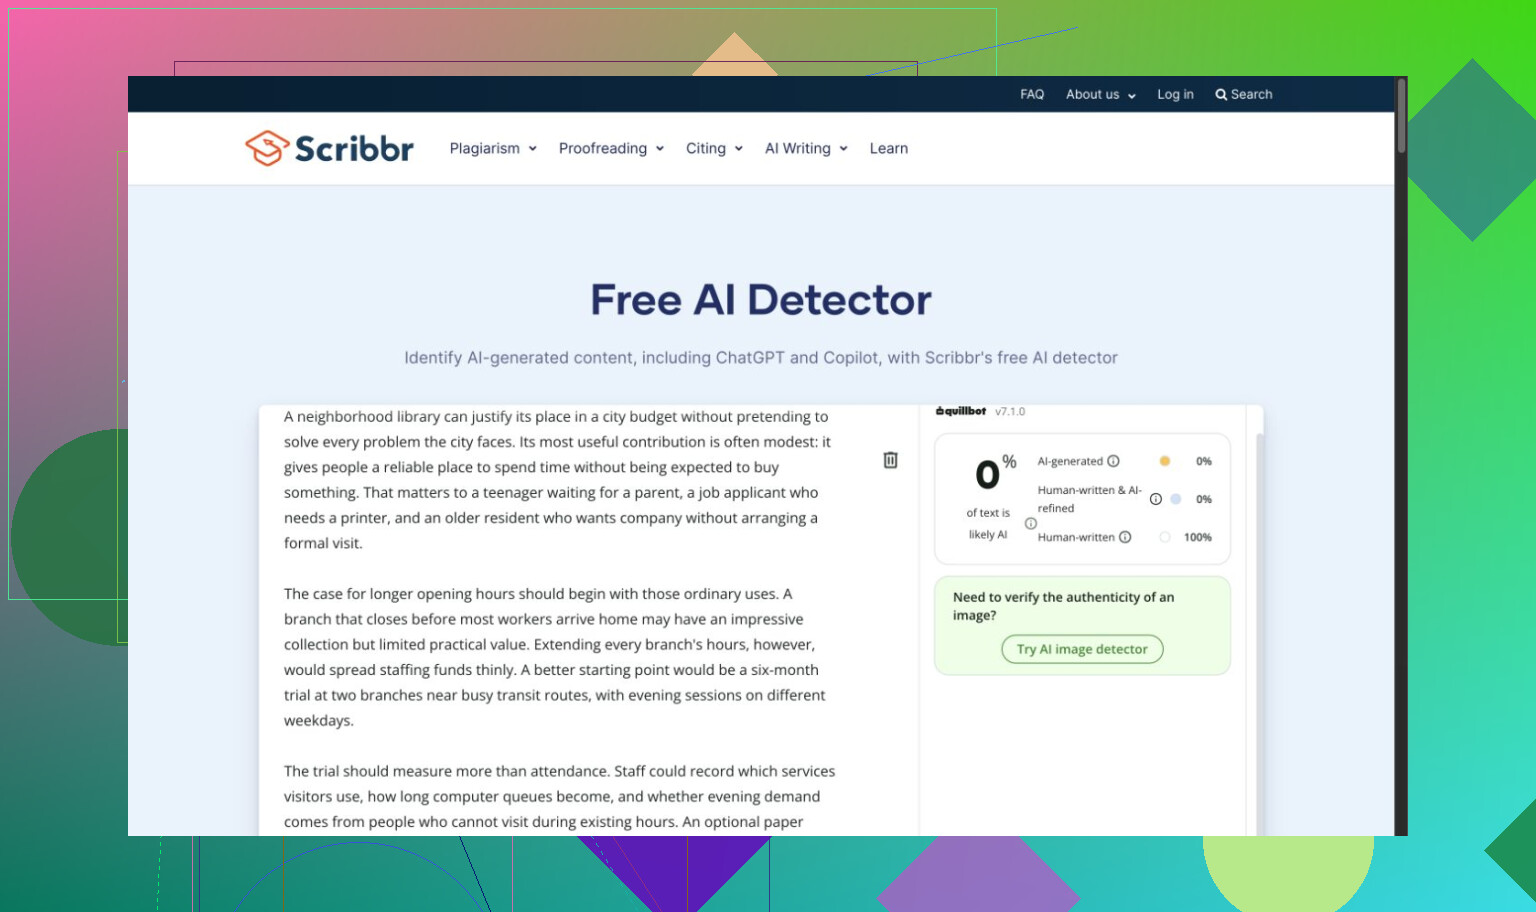
The opposite error showed up elsewhere. QuillBot called all four generated passages 100% human-written. Scribbr accepted both the essay and Carroll as human-written on a follow-up attempt. Its visible QuillBot branding also kept me from treating those sites as independent votes.
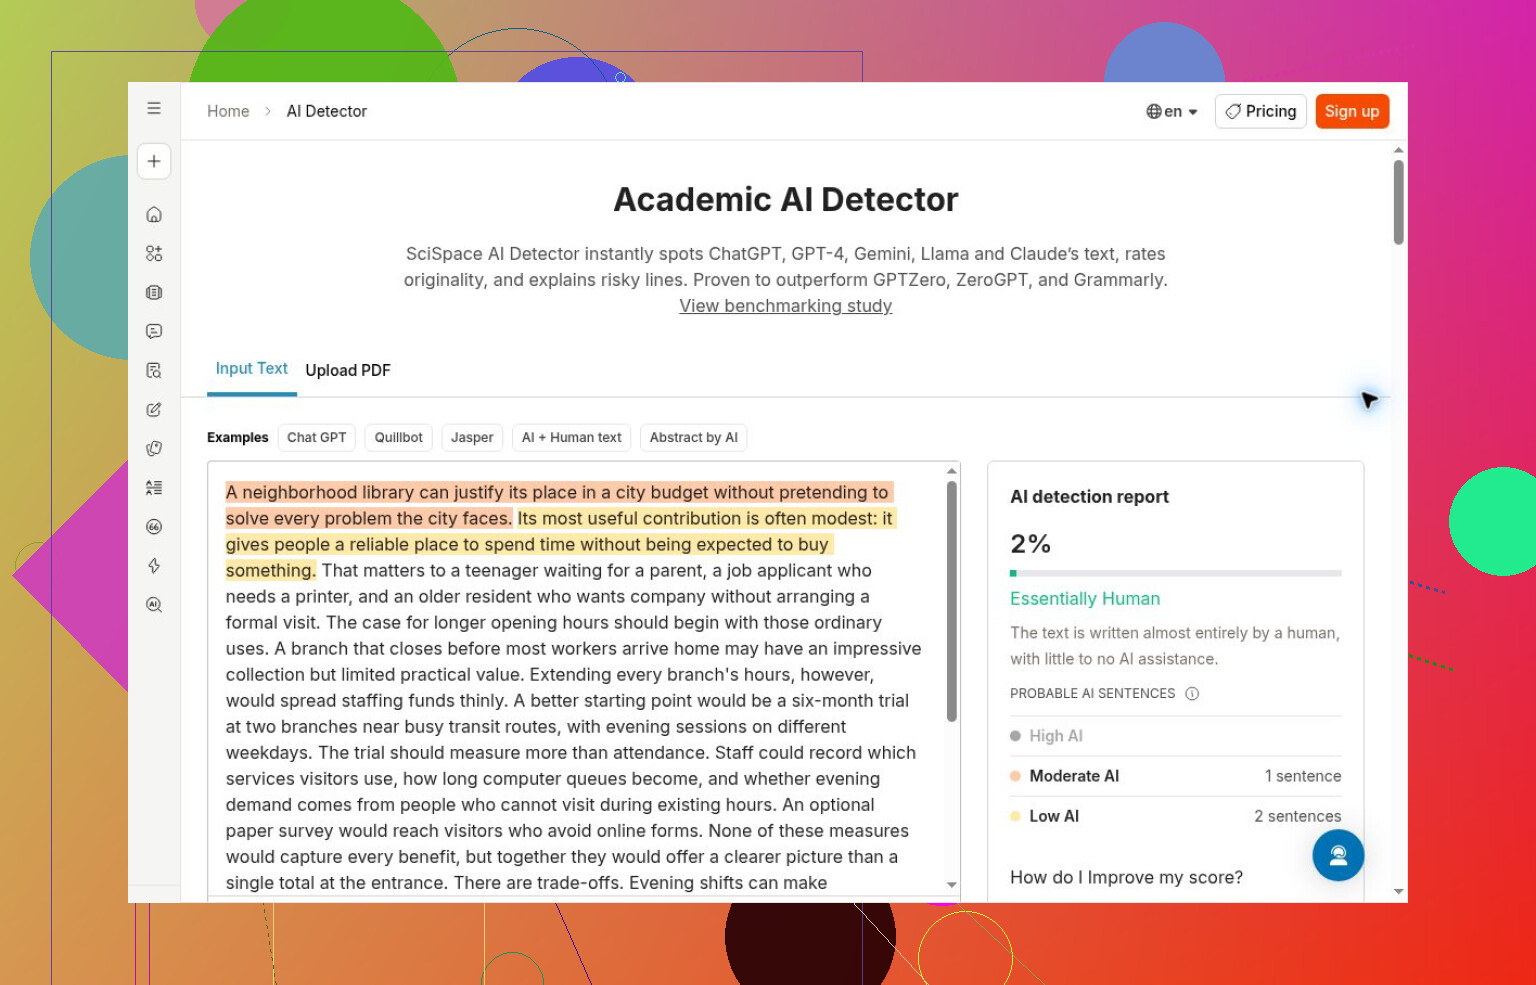
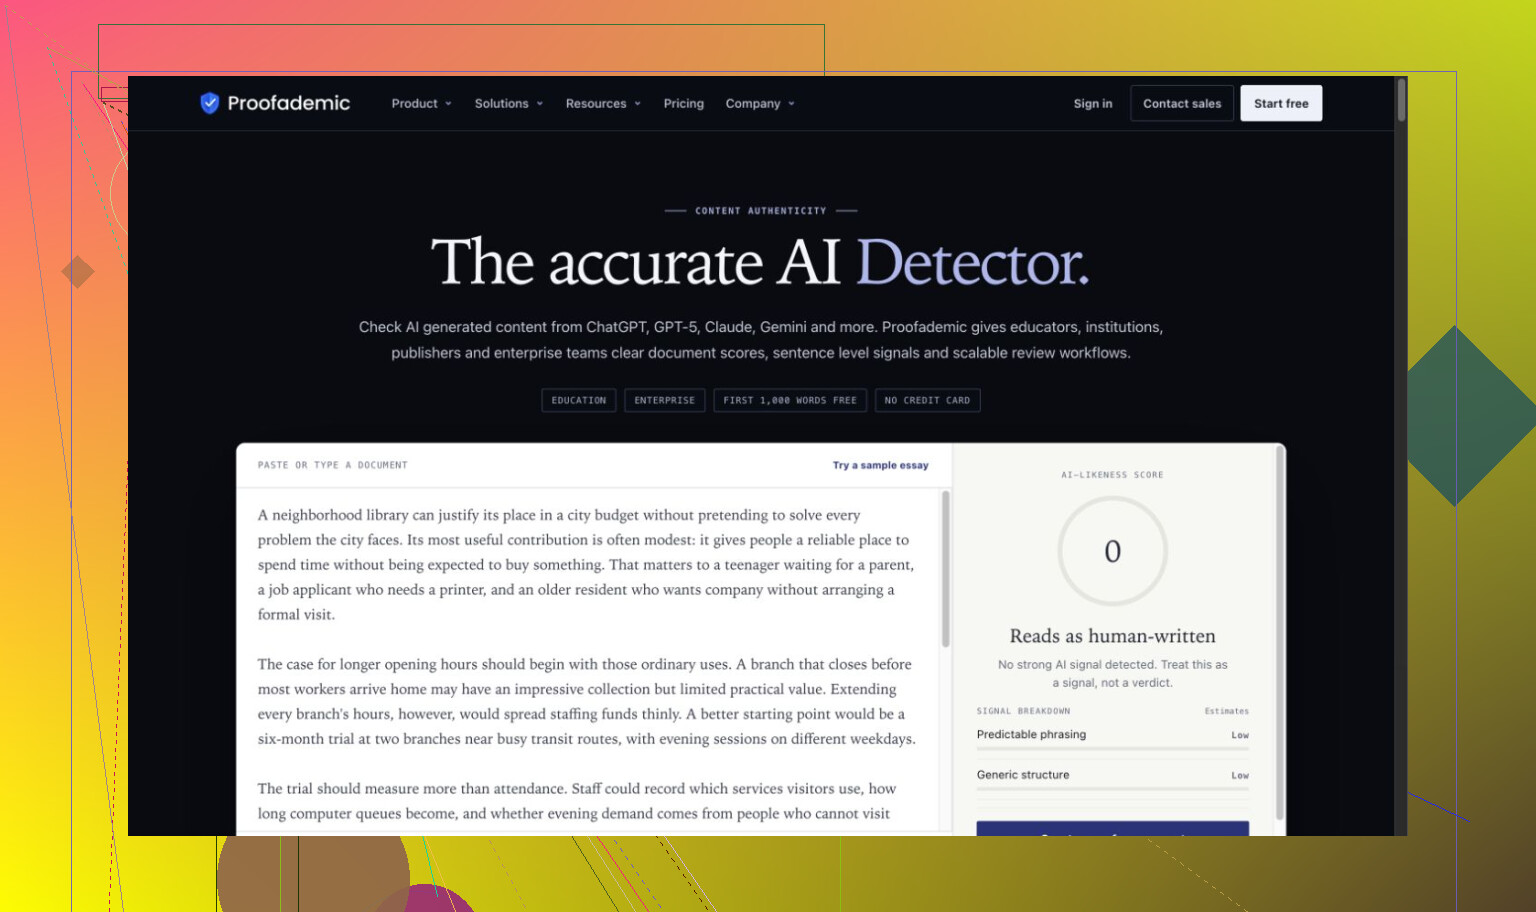
SciSpace returned 2% AI for the generated essay. Proofademic’s public demo settled at 0/100 AI-likeness for both the essay and Carroll. Surfer gave the essay, story, and Carroll a 0% chance of AI writing. Those were completed results, not guesses about inaccessible reports.
What I actually compared
I checked 24 tools on October 2–3, 2026, using six unchanged English passages. The generated material covered an essay, a business memo, a paraphrase, and a fictional personal story. Carroll supplied the human control, with a lightly AI-edited version as the mixed example.
Some passages were related. A literary excerpt isn’t a substitute for a broad sample of modern human writing, and the edited version isn’t a second pure-human control.
I counted only finished checks. I also kept confidence, probability, and estimated AI share separate. They aren’t interchangeable measurements. The images record results or access conditions, not evidence that every tool completed the same workload.
Correct calls came with different limits
Clever finished the full set without signup. It caught the generated passages and gave Carroll Human 99%, but gave the lightly edited version that same label. Some sentence colors disagreed with the headline, and explanation tags weren’t always useful. I didn’t test its advertised unlimited access at scale.
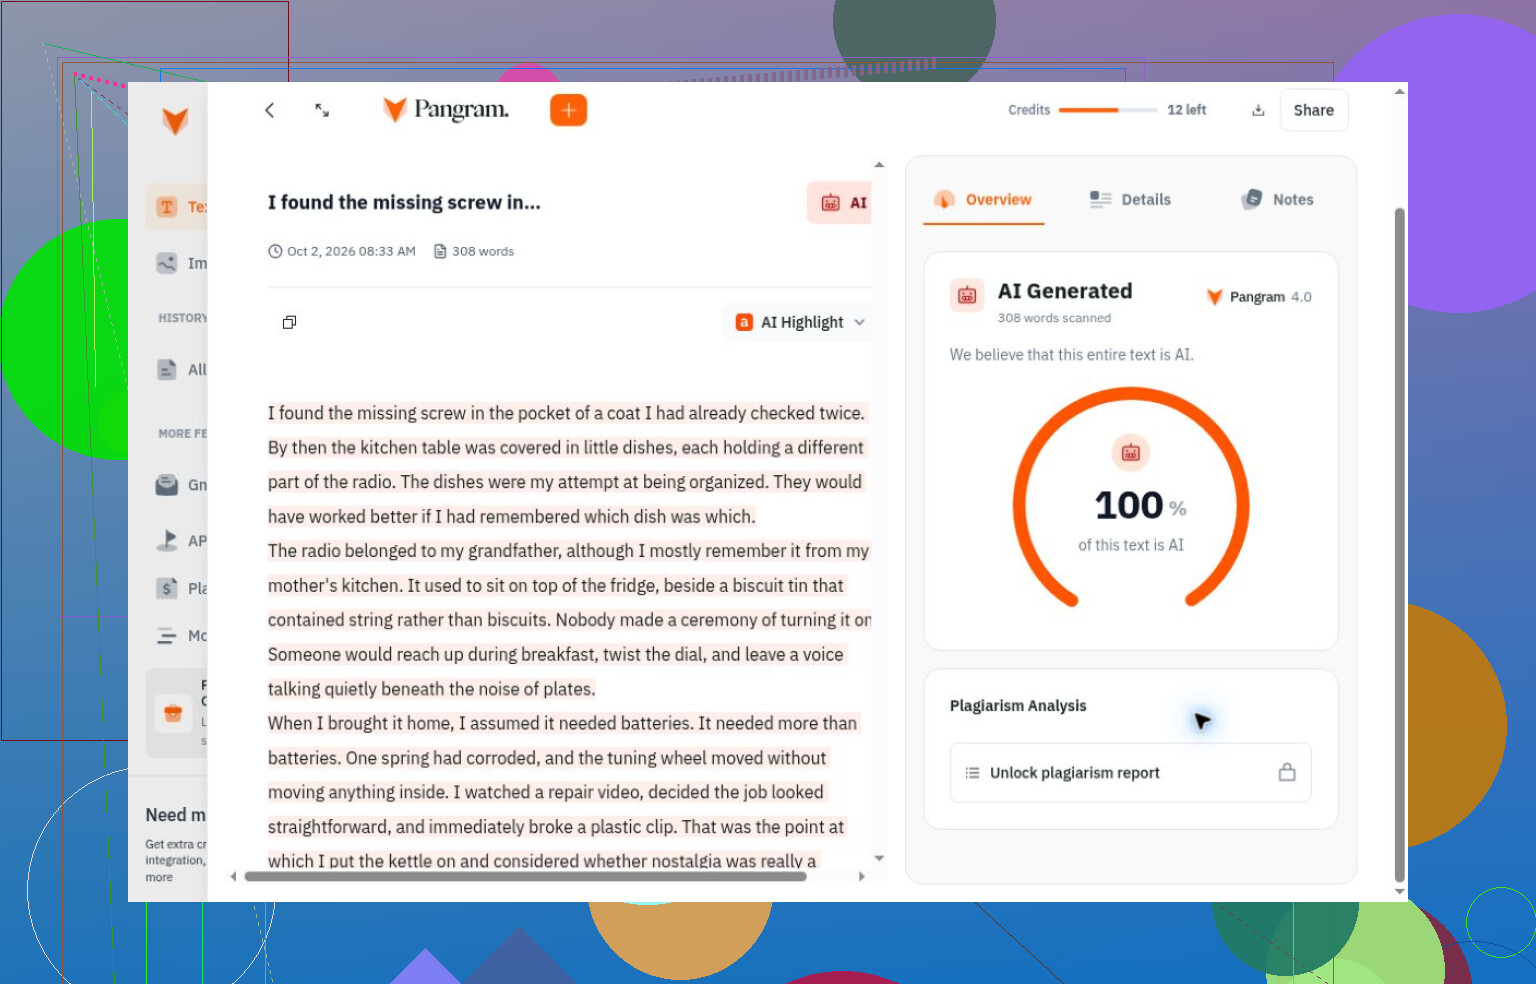
Pangram correctly identified the generated texts it checked and accepted Carroll. Its allowance ended after five checks, with usage depending on length. It also treated the edited excerpt as entirely human.
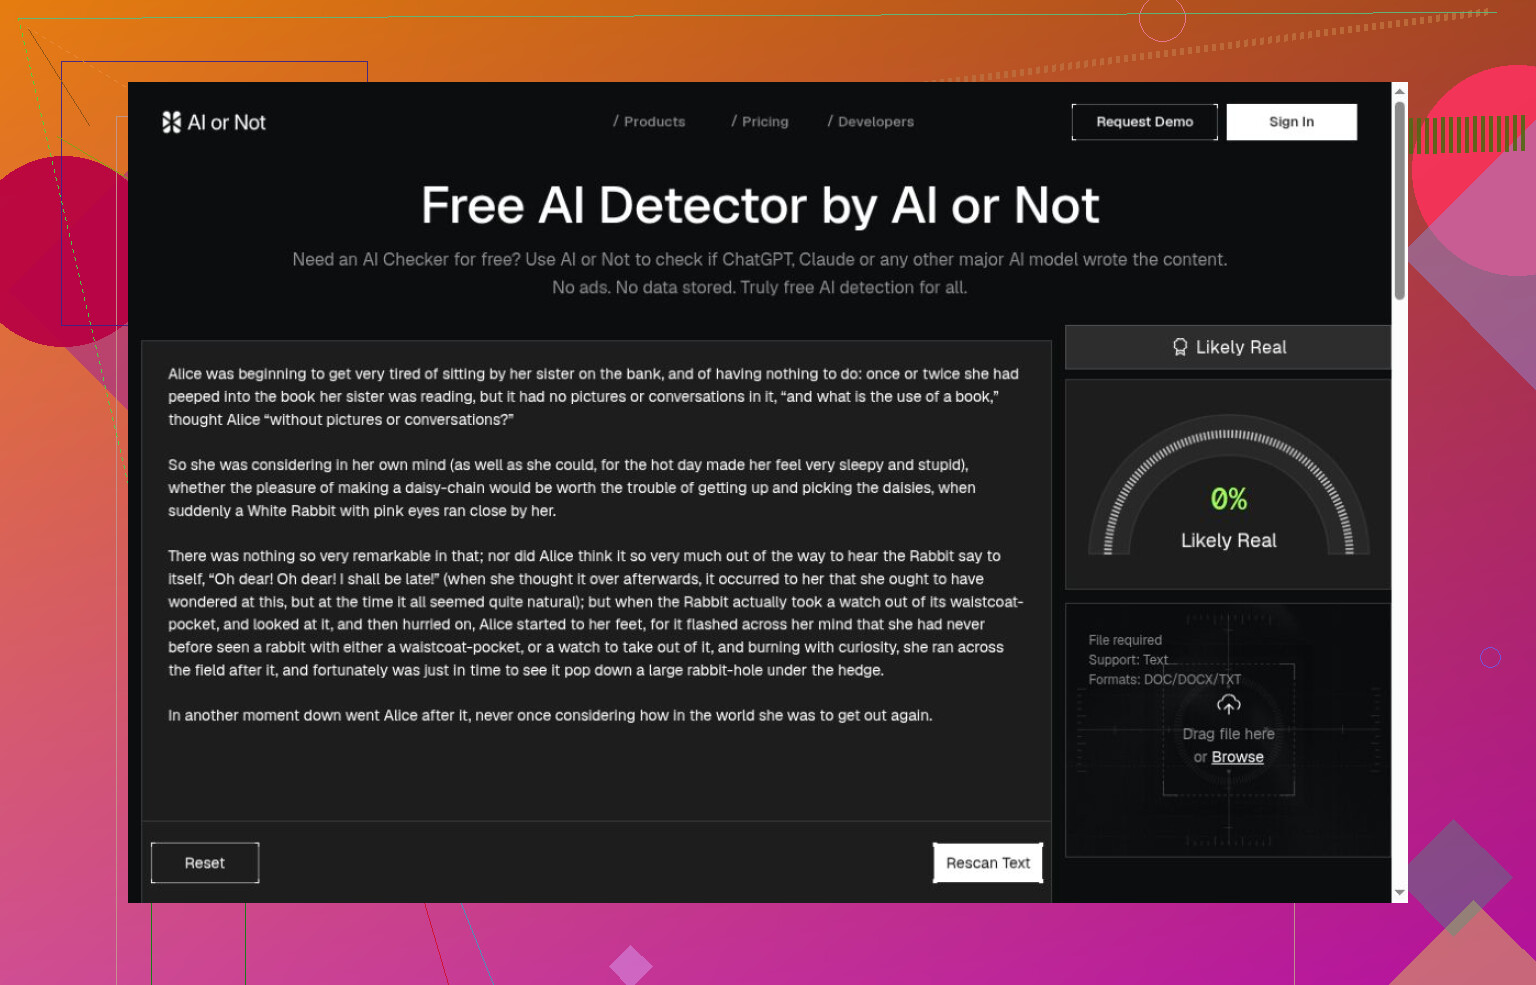
Originality.ai correctly labeled its completed AI and human examples. I selected 15% AI Allowance; its 100% confidence described a threshold-based verdict, not the percentage of generated words. AI or Not also got its completed guest examples right, but I didn’t test mixed writing or other media there.
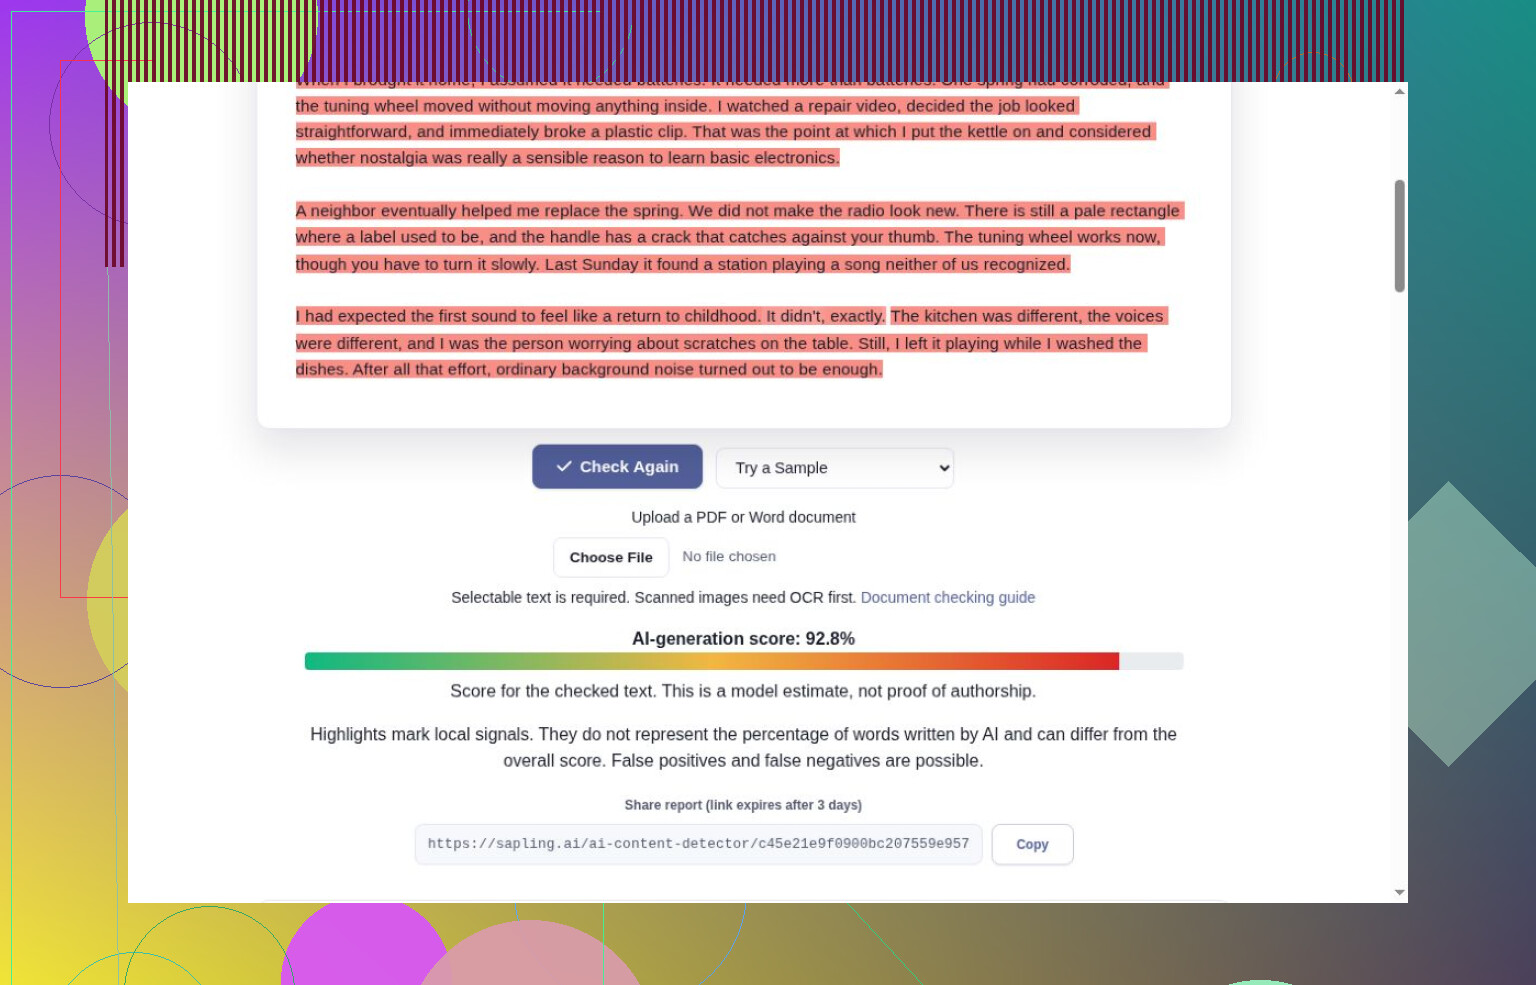
Sapling correctly handled the complete story and human excerpt. Its essay result covered only 2,000 of 2,070 characters.
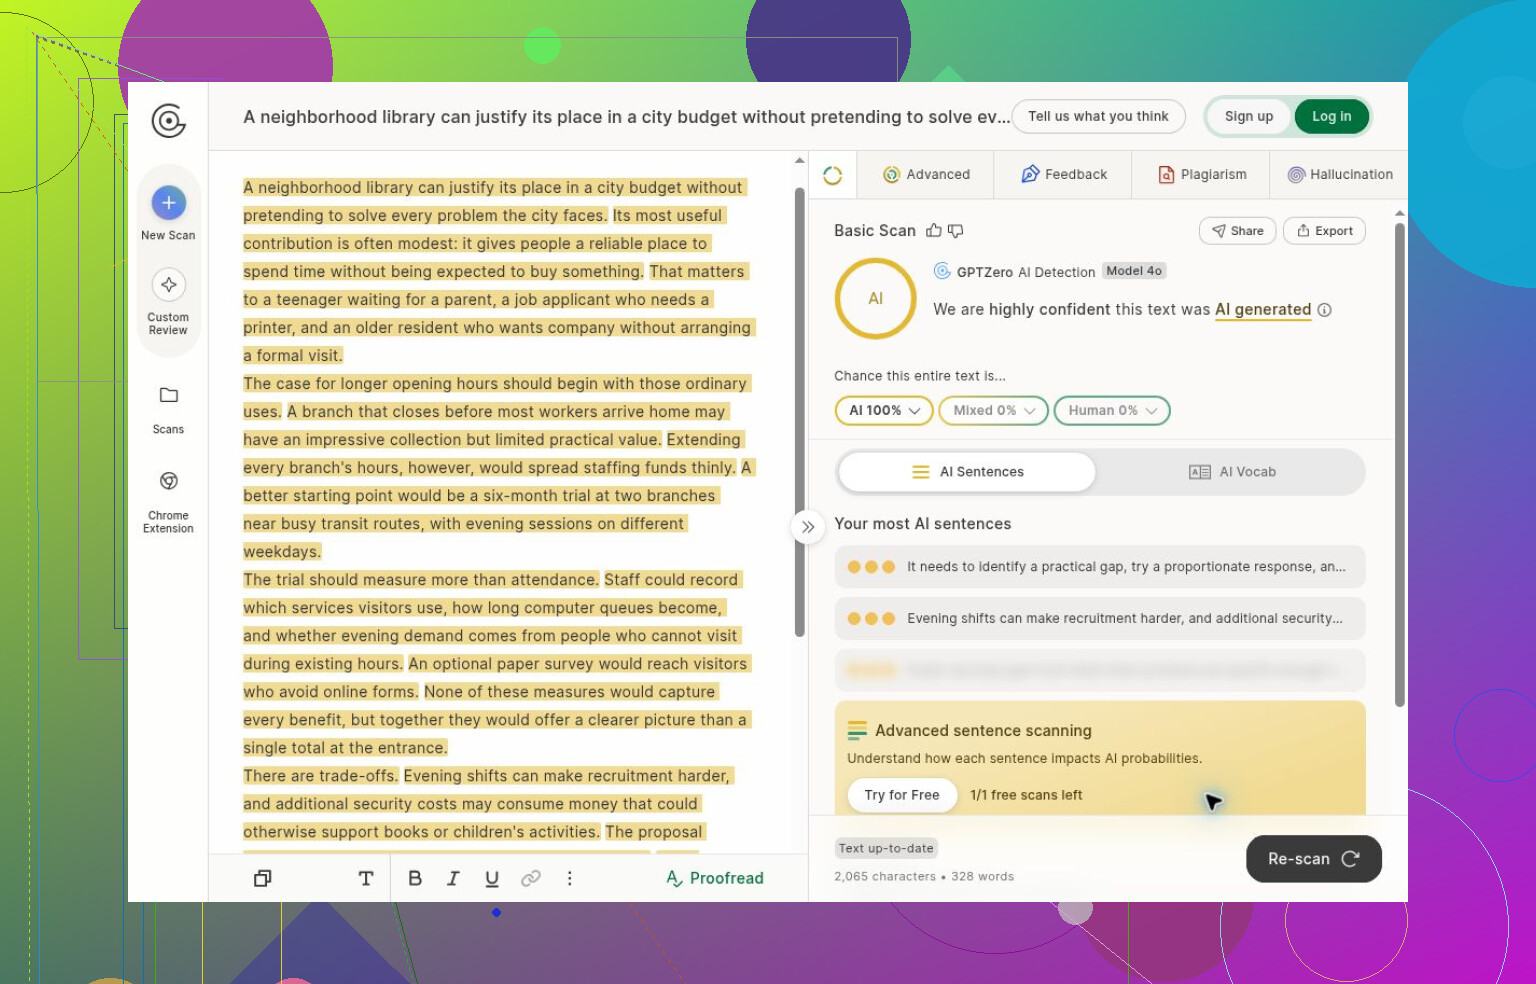
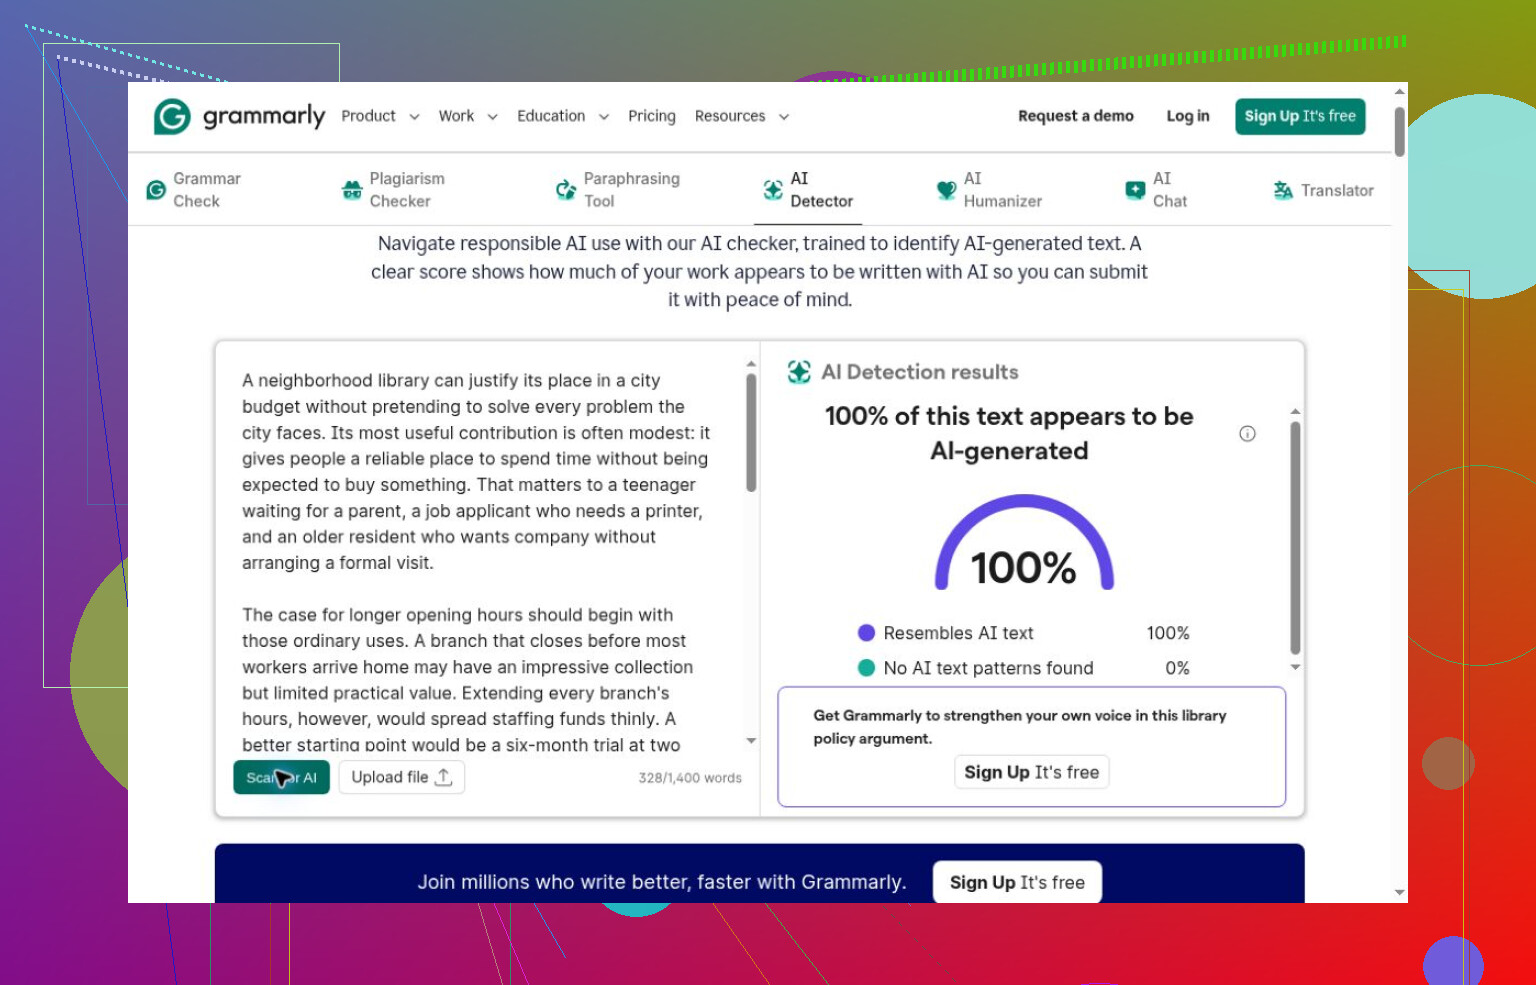
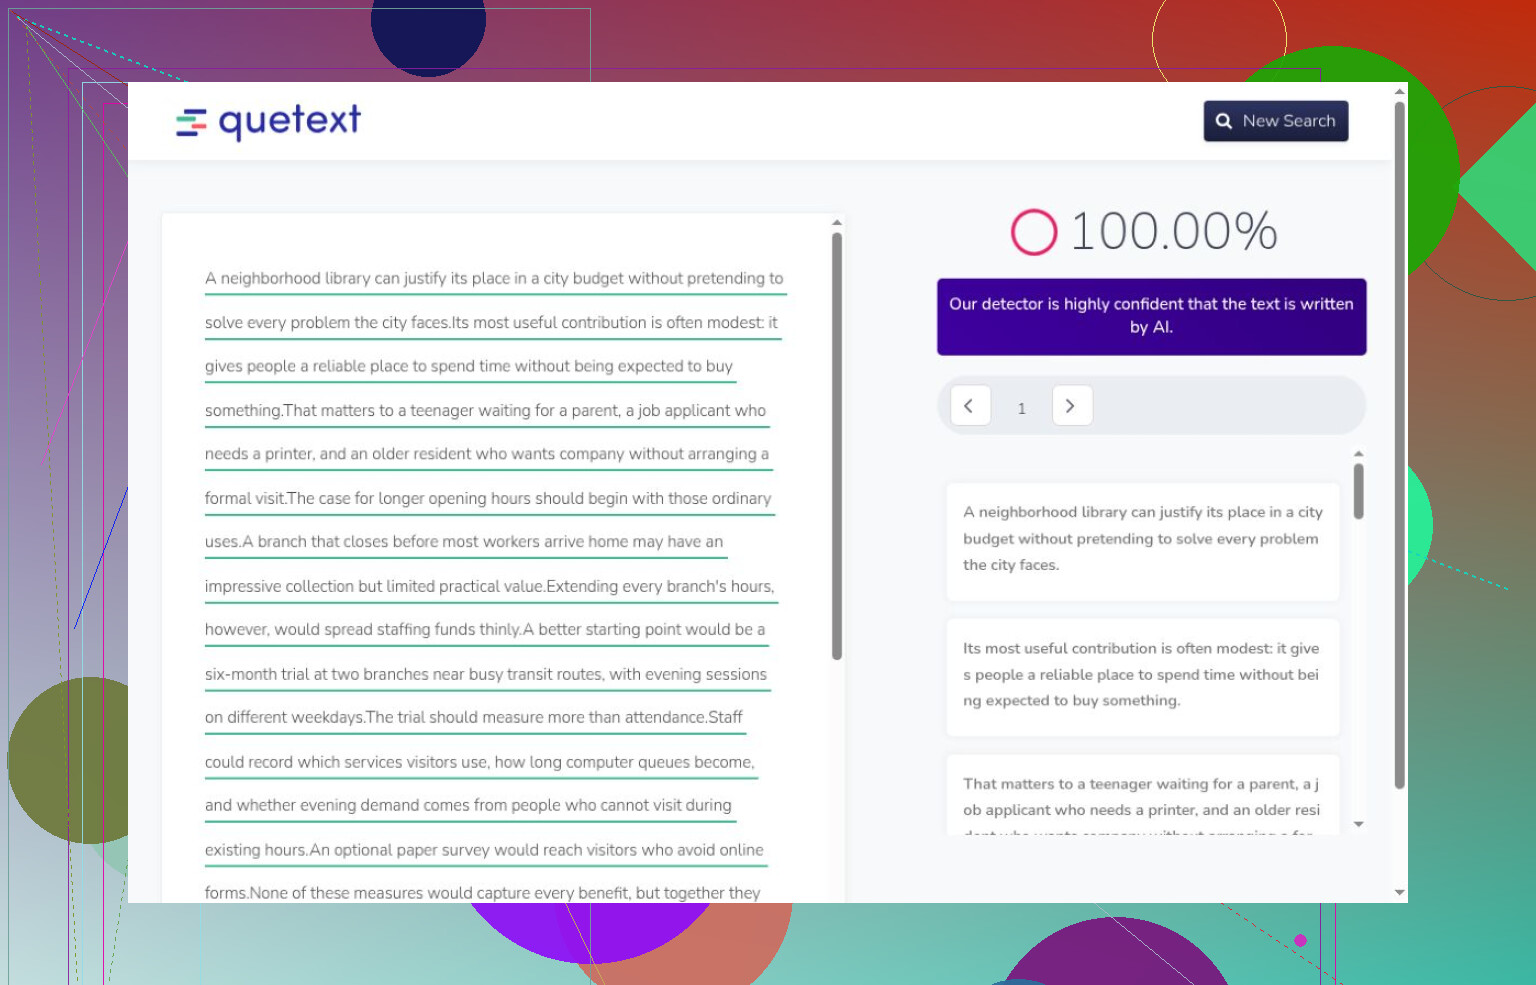
GPTZero caught three generated inputs before signup intervened. An old score remained after I changed the text, so I didn’t count that display as another result. Grammarly and Quetext each caught the essay before account prompts stopped further checks. None of those limited runs supplied a human result.
Access problems weren’t detection failures
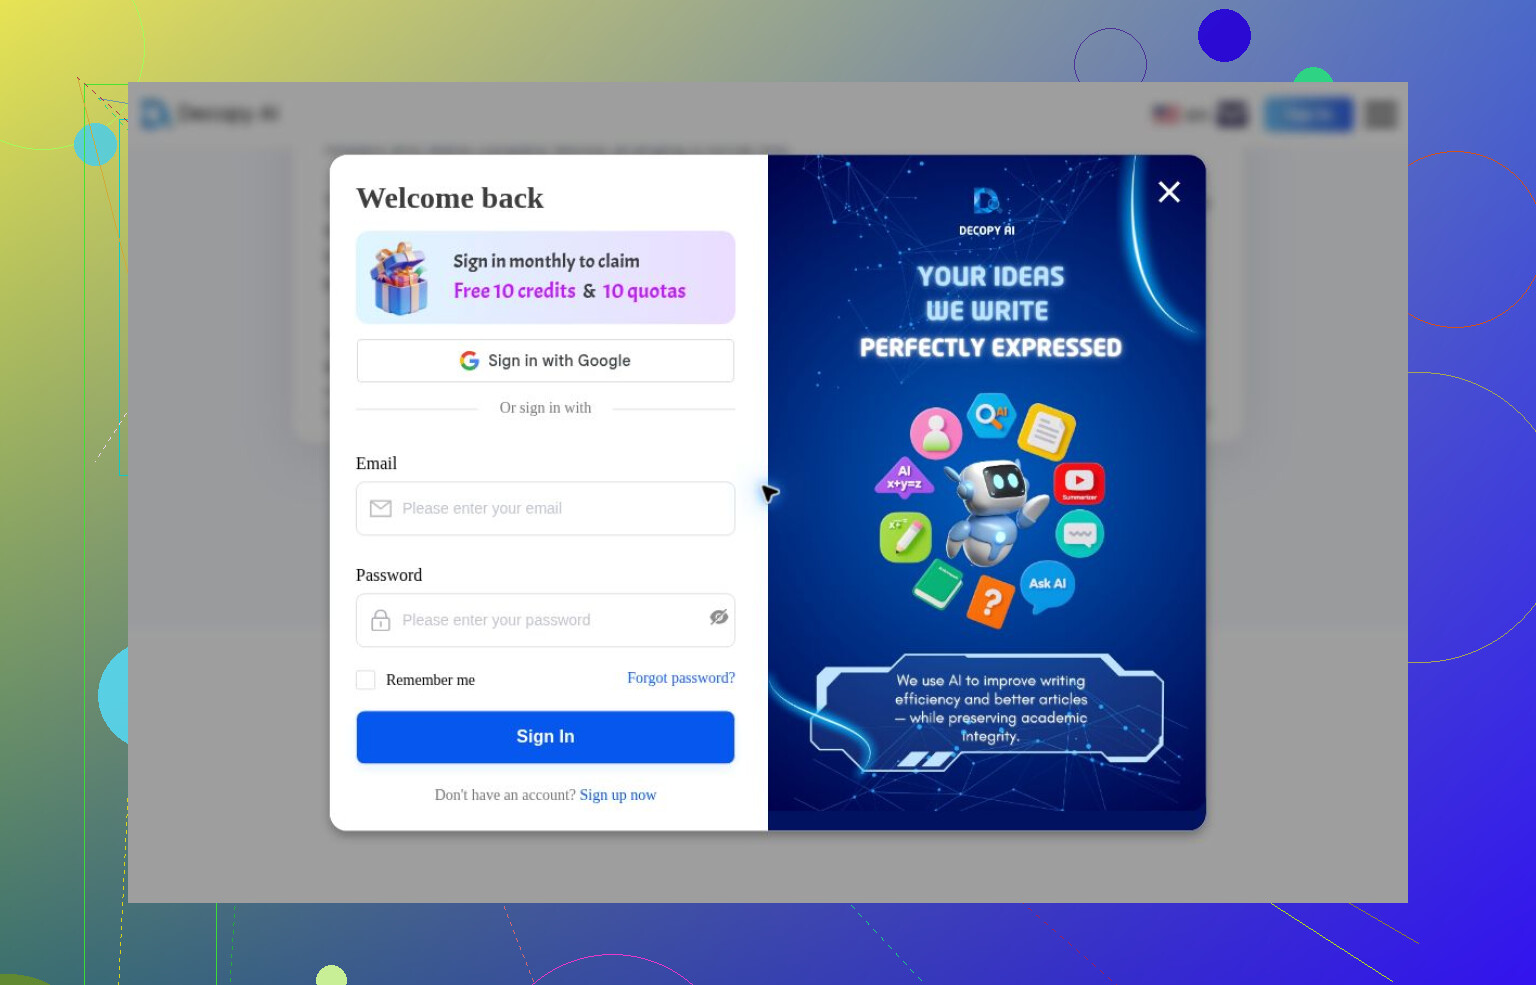
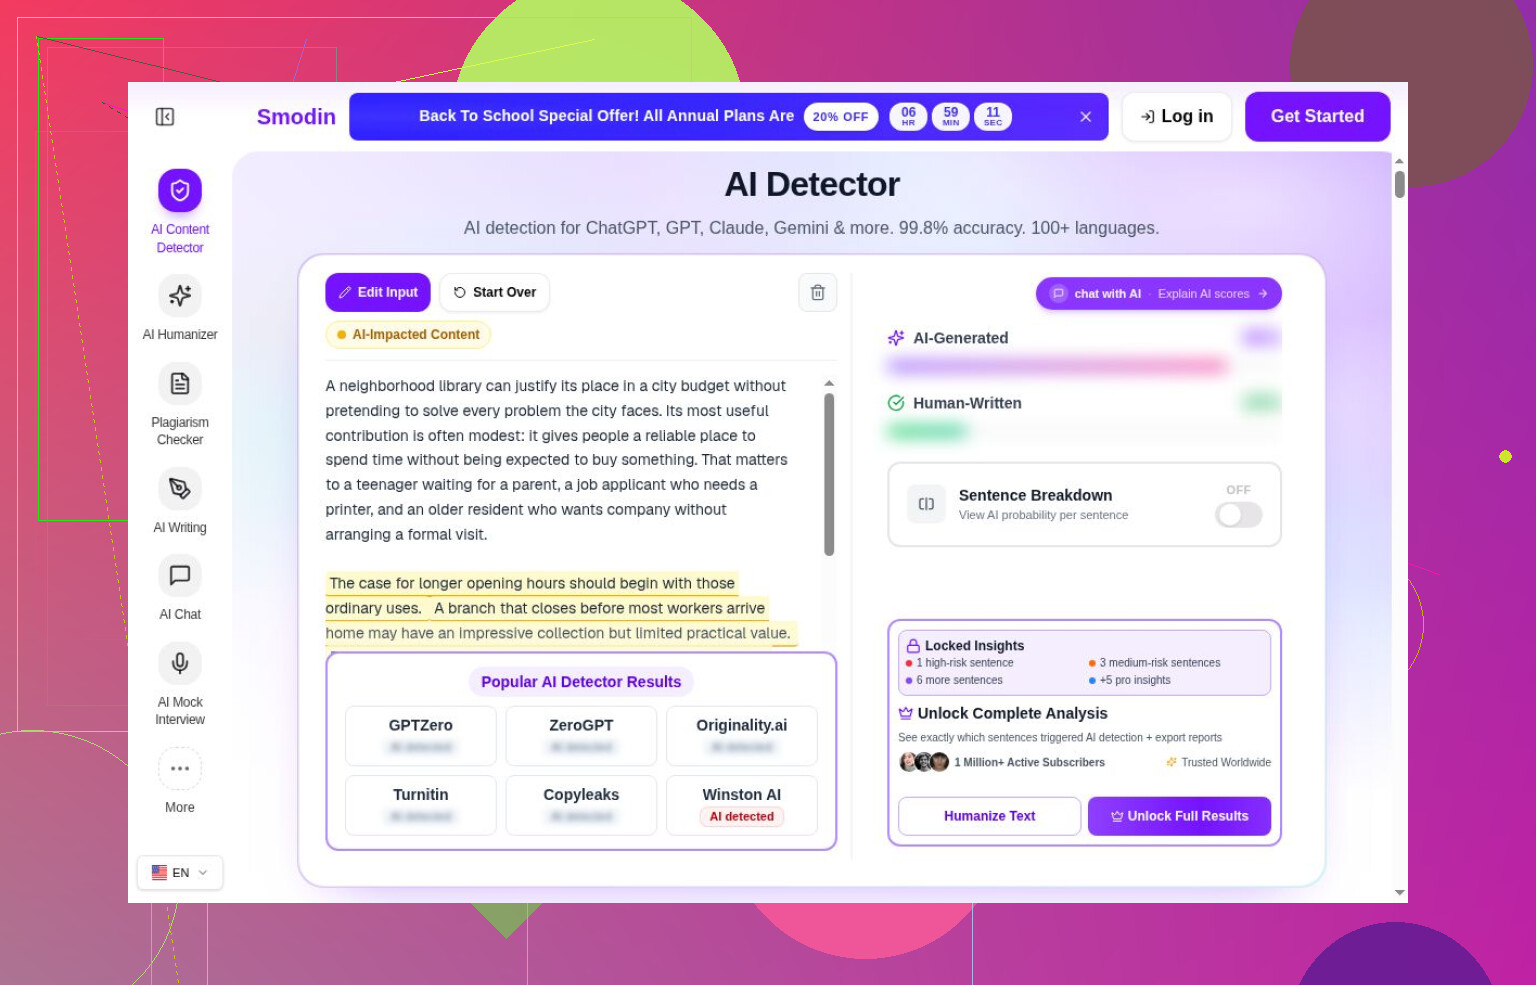
Decopy opened a login dialog when I submitted the essay. Smodin showed highlights but hid the headline percentages. Neither gave me a usable detection result.
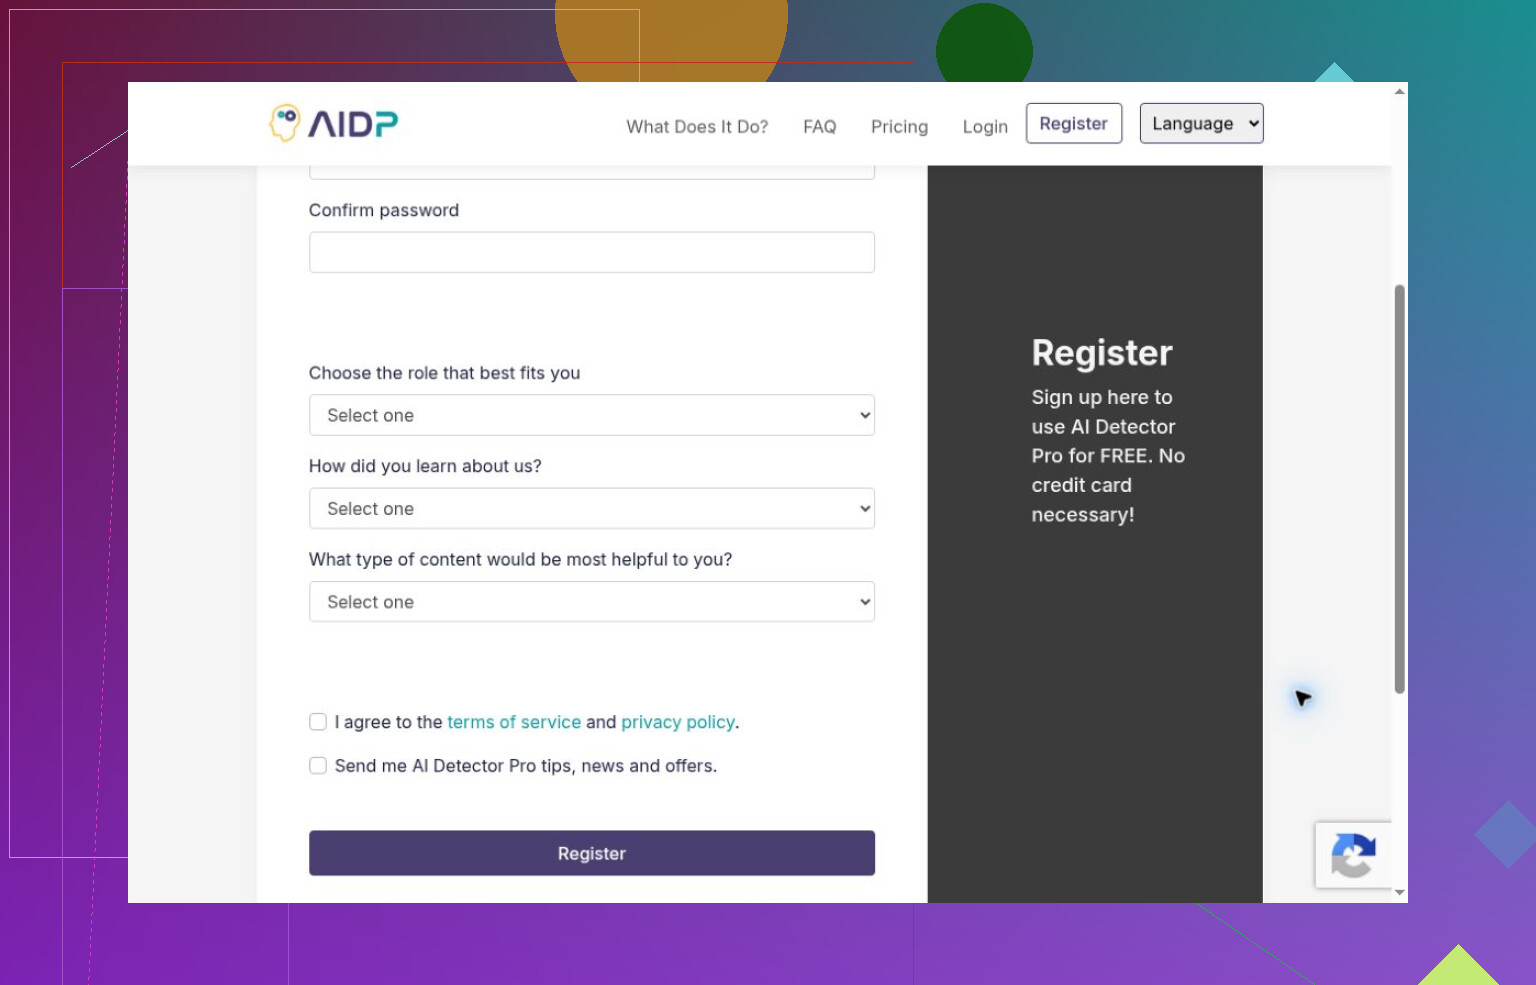
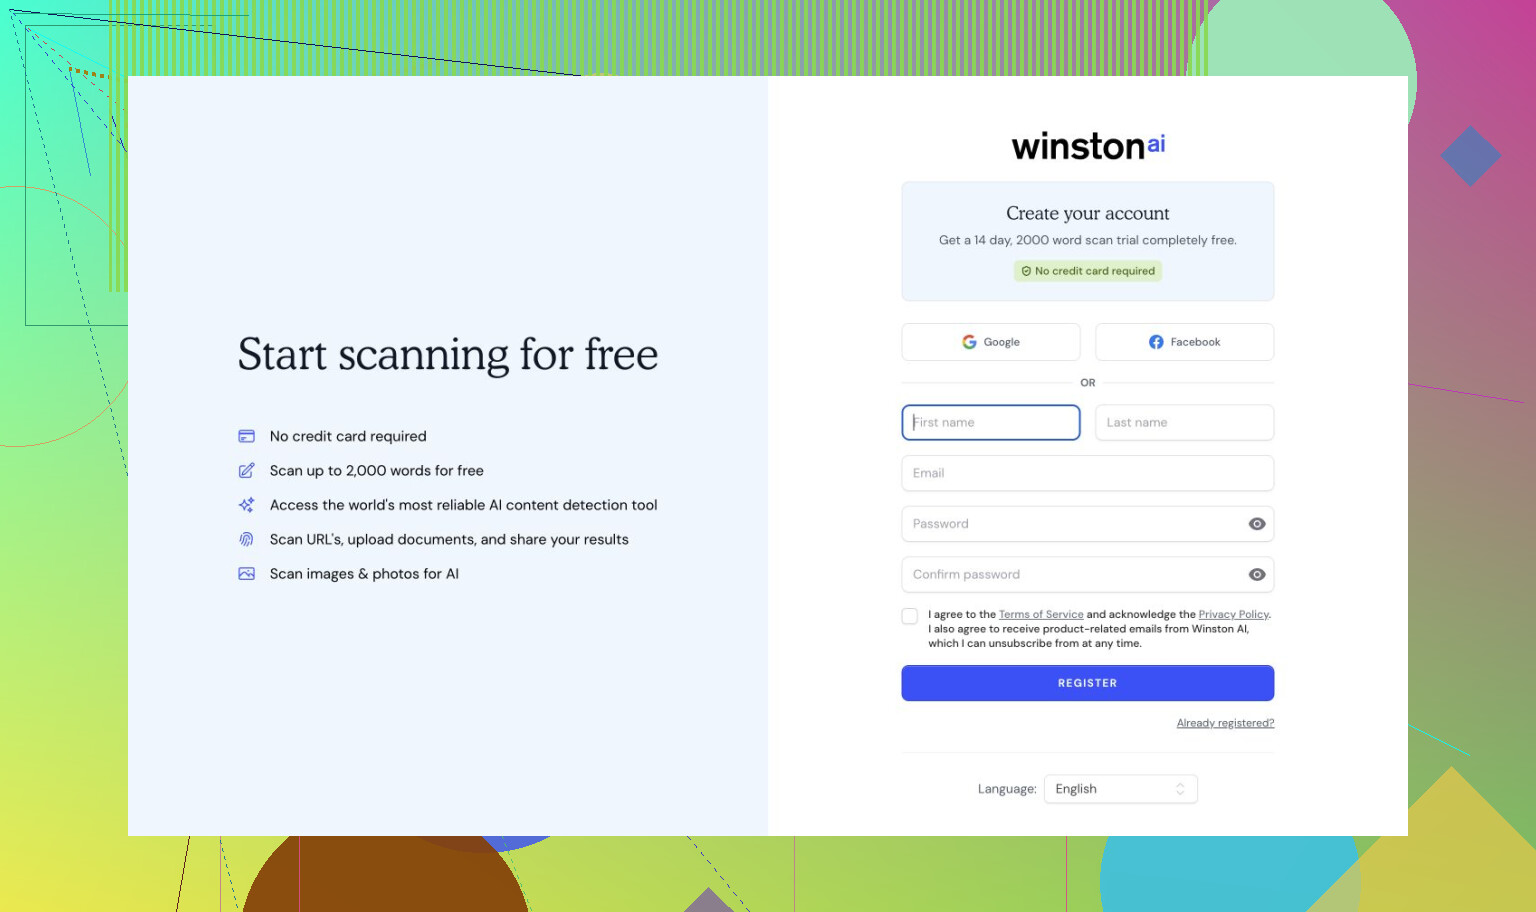
AI Detector Pro and Winston AI required registration before scanning. Turnitin needed institutional access and a license add-on. Copyleaks loaded its guest interface, but I stopped over applicable-use terms. Those cases don’t establish poor accuracy or unavailable free scanning.
Hive’s inspected demo handled media rather than prose; I didn’t configure its text extension or API. ContentDetector.AI sent me to a Moxby extension listing, which I didn’t install. Humanly remained an Apple store listing review, with a free download and in-app purchases, not a tested scanning allowance.
My choice is narrower than a winner’s list
I didn’t test paid workflows or multilingual coverage. Account requirements and allowances also need checking again before regular use.
I’d keep drafts and sources when a result is disputed, rather than turn a score into an accusation. For my own occasional free checks, Clever is my pick because I could finish the set and it separated the known generated passages from the human control. I wouldn’t trust it, or any other tool in this comparison, to settle authorship.